<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://tlouarn.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://tlouarn.com/" rel="alternate" type="text/html" /><updated>2026-05-16T14:11:15+00:00</updated><id>https://tlouarn.com/feed.xml</id><title type="html">tlouarn</title><subtitle>Personal blog where I document key ideas from programming, software engineering, quantitative finance and blockchain.
</subtitle><author><name>tlouarn</name></author><entry><title type="html">Working with timezones in Python</title><link href="https://tlouarn.com/2026/03/02/working-with-timezones-in-python.html" rel="alternate" type="text/html" title="Working with timezones in Python" /><published>2026-03-02T00:00:00+00:00</published><updated>2026-03-02T00:00:00+00:00</updated><id>https://tlouarn.com/2026/03/02/working-with-timezones-in-python</id><content type="html" xml:base="https://tlouarn.com/2026/03/02/working-with-timezones-in-python.html"><![CDATA[<p><img src="/assets/images/tlouarn-working-with-timezones-in-python-banner.png" alt="Working with timezones in Python banner" /></p>

<h1 id="what-are-timezones">What are timezones</h1>

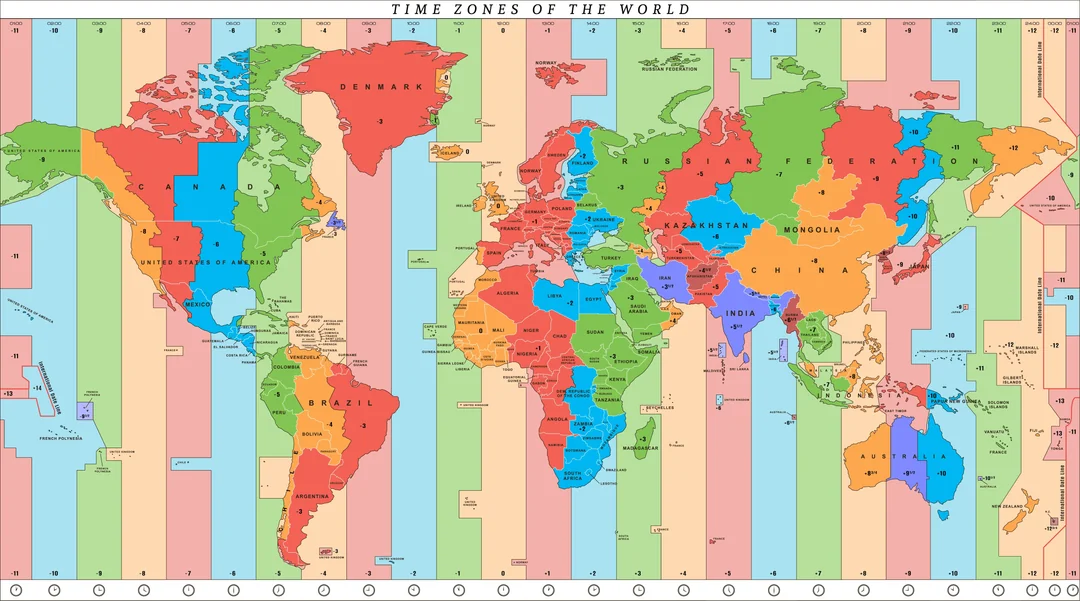
<p>Time zones are a way of mapping the Earth’s 24-hour rotation into practical local times so that noon corresponds roughly to when the sun is highest in the sky. The Earth is divided into longitudinal regions, each offset from Coordinated Universal Time (<strong>UTC</strong>), which serves as the global reference clock. Historically, timekeeping was local and solar-based until railways and telecommunications forced standardization in the 19th century, leading to the adoption of standardized time zones and eventually UTC as the universal baseline.</p>

<p>In modern computing, time zones are represented using the IANA Time Zone Database (also called the <strong>tz</strong> or <strong>Olson</strong> database), which encodes not just fixed offsets (like UTC+1) but also historical changes and daylight saving rules for each region. In Python, the modern standard library tool for working with time zones is <code class="language-plaintext highlighter-rouge">zoneinfo</code> (introduced in Python 3.9 via PEP 615), which replaces earlier reliance on third-party packages like <code class="language-plaintext highlighter-rouge">pytz</code>.</p>

<p><img src="/assets/images/tlouarn-working-with-timezones-in-python-timezones.webp" alt="Timezones" /></p>

<h1 id="naive-vs-localized-timestamps">Naive vs localized timestamps</h1>

<p>One of the most important concepts in time zone handling is the difference between <strong>naive</strong> and <strong>aware</strong> timestamps. A naive datetime object in Python has no attached time zone information, which means it does not represent an absolute point in time but only a <strong>wall clock</strong> value.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">datetime</span> <span class="kn">import</span> <span class="n">datetime</span>

<span class="n">naive_ts</span> <span class="o">=</span> <span class="n">datetime</span><span class="p">(</span><span class="mi">2026</span><span class="p">,</span> <span class="mi">3</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">14</span><span class="p">,</span> <span class="mi">30</span><span class="p">,</span> <span class="mi">00</span><span class="p">)</span>
</code></pre></div></div>

<p>The problem arises when such a timestamp is interpreted differently depending on the system or context. For example, the above example could mean <strong>14:30</strong> in Paris, New York or Tokyo. Without explicit context, Python assumes a timestamp is in the system’s local time zone when converting it. This becomes dangerous since it can produce inconsistent results across machines:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Assuming the machine's local time zone is Europe/Paris
</span><span class="n">naive_ts</span> <span class="o">=</span> <span class="n">datetime</span><span class="p">(</span><span class="mi">2026</span><span class="p">,</span> <span class="mi">3</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">14</span><span class="p">,</span> <span class="mi">30</span><span class="p">,</span> <span class="mi">0</span><span class="p">)</span>
<span class="n">utc_ts</span> <span class="o">=</span> <span class="n">naive_ts</span><span class="p">.</span><span class="n">astimezone</span><span class="p">(</span><span class="n">ZoneInfo</span><span class="p">(</span><span class="s">"UTC"</span><span class="p">))</span>

<span class="o">&gt;&gt;&gt;</span> <span class="n">utc_ts</span>
<span class="mi">2026</span><span class="o">-</span><span class="mi">03</span><span class="o">-</span><span class="mi">02</span> <span class="mi">13</span><span class="p">:</span><span class="mi">30</span><span class="p">:</span><span class="mi">00</span><span class="o">+</span><span class="mi">00</span><span class="p">:</span><span class="mi">00</span>
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Assuming the machine's local time zone is America/New_York
</span><span class="n">naive_ts</span> <span class="o">=</span> <span class="n">datetime</span><span class="p">(</span><span class="mi">2026</span><span class="p">,</span> <span class="mi">3</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">14</span><span class="p">,</span> <span class="mi">30</span><span class="p">,</span> <span class="mi">0</span><span class="p">)</span>
<span class="n">utc_ts</span> <span class="o">=</span> <span class="n">naive_ts</span><span class="p">.</span><span class="n">astimezone</span><span class="p">(</span><span class="n">ZoneInfo</span><span class="p">(</span><span class="s">"UTC"</span><span class="p">))</span>

<span class="o">&gt;&gt;&gt;</span> <span class="n">utc_ts</span>
<span class="mi">2026</span><span class="o">-</span><span class="mi">03</span><span class="o">-</span><span class="mi">02</span> <span class="mi">19</span><span class="p">:</span><span class="mi">30</span><span class="p">:</span><span class="mi">00</span><span class="o">+</span><span class="mi">00</span><span class="p">:</span><span class="mi">00</span>
</code></pre></div></div>

<p>The correct approach is to always make timestamps timezone-aware before conversion. When naive datetimes represent only a local interpretation of a clock reading, timezone-aware timestamps represent an absolute point in time. Once a timestamp is aware, conversions become <strong>reliable</strong> and <strong>deterministic</strong>. In our above example, assuming we meant <strong>14:30</strong> in Paris, making the timestamp timezone-aware will guarantee the same conversion to UTC whether the machine running the code is located in Paris or in New York:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">datetime</span> <span class="kn">import</span> <span class="n">datetime</span>
<span class="kn">from</span> <span class="nn">zoneinfo</span> <span class="kn">import</span> <span class="n">ZoneInfo</span>

<span class="c1"># Assuming the system's local time zone is America/New_York
</span><span class="n">paris_ts</span> <span class="o">=</span> <span class="n">datetime</span><span class="p">(</span><span class="mi">2026</span><span class="p">,</span> <span class="mi">3</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">14</span><span class="p">,</span> <span class="mi">30</span><span class="p">,</span> <span class="mi">0</span><span class="p">,</span> <span class="n">tzinfo</span><span class="o">=</span><span class="n">ZoneInfo</span><span class="p">(</span><span class="s">"Europe/Paris"</span><span class="p">))</span>
<span class="n">utc_ts</span> <span class="o">=</span> <span class="n">paris_ts</span><span class="p">.</span><span class="n">astimezone</span><span class="p">(</span><span class="n">ZoneInfo</span><span class="p">(</span><span class="s">"UTC"</span><span class="p">))</span>

<span class="o">&gt;&gt;&gt;</span> <span class="n">utc_ts</span>
<span class="mi">2026</span><span class="o">-</span><span class="mi">03</span><span class="o">-</span><span class="mi">02</span> <span class="mi">13</span><span class="p">:</span><span class="mi">30</span><span class="p">:</span><span class="mi">00</span><span class="o">+</span><span class="mi">00</span><span class="p">:</span><span class="mi">00</span>
</code></pre></div></div>

<h1 id="the-dst-complexity">The DST complexity</h1>

<p>Daylight Saving Time (<strong>DST</strong>) adds another layer of complexity to time zone handling because it introduces seasonal shifts in local time offsets. DST is the practice of moving clocks forward in Spring and backward in Autumn to extend evening daylight hours during warmer months.</p>

<p>Not all regions observe DST, and those that do often implement it differently. For example, in the United States, DST typically begins on the second Sunday in March and ends on the first Sunday in November, shifting time zones such as Eastern Time from UTC−5 (EST) to UTC−4 (EDT). In contrast, most European countries, begin DST on the last Sunday in March and end it on the last Sunday in October, shifting from UTC+0 (GMT) to UTC+1 (BST). This mismatch means that for several weeks each year, the time difference between America and Europe changes.</p>

<pre class="mermaid">
gantt
    title DST 2026 — US vs UK
    dateFormat  YYYY-MM-DD
    axisFormat  %b
    todayMarker off

    section US

    US Winter   :us_w1, 2026-01-01, 2026-03-08
    US Summer   :us_s, 2026-03-08, 2026-11-01
    US Winter   :us_w2, 2026-11-01, 2026-12-31

    section UK

    UK Winter   :uk_w1, 2026-01-01, 2026-03-29
    UK Summer   :uk_s, 2026-03-29, 2026-10-25
    UK Winter   :uk_w2, 2026-10-25, 2026-12-31
</pre>

<p>Fortunately, <code class="language-plaintext highlighter-rouge">zoneinfo</code> handles these transitions automatically using the IANA database, so converting timestamps across zones correctly reflects these offsets without manual adjustment. However, care must still be taken when working with local times around DST transitions, because some local times do not exist (spring forward gaps) or occur twice (fall back ambiguity).</p>]]></content><author><name>tlouarn</name></author><category term="python" /><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">Running GitHub Pages locally</title><link href="https://tlouarn.com/2025/09/14/running-github-pages-locally.html" rel="alternate" type="text/html" title="Running GitHub Pages locally" /><published>2025-09-14T00:00:00+00:00</published><updated>2025-09-14T00:00:00+00:00</updated><id>https://tlouarn.com/2025/09/14/running-github-pages-locally</id><content type="html" xml:base="https://tlouarn.com/2025/09/14/running-github-pages-locally.html"><![CDATA[<p>If, like me, you are building a personal site or project page with <a href="https://docs.github.com/en/pages">GitHub Pages</a>, you have probably wanted to preview it locally before pushing changes live. Luckily, with <strong>Docker</strong> and <strong>Jekyll</strong>, you can spin up a local version of your site in minutes, running in a clean, isolated container. Here is a step-by-step guide tested under Windows 11 Professional Edition.</p>

<h1 id="install-docker-for-windows">Install Docker for Windows</h1>

<p>If you haven’t already, download and install <a href="https://www.docker.com/products/docker-desktop/">Docker Desktop</a>. This will let you run containerized services on your machine. By default, Docker Desktop will run with WSL 2 (Windows Subsystem for Linux).</p>

<p>Once installed, check that Docker is working by opening a terminal window and typing:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker <span class="nt">--version</span>
</code></pre></div></div>

<h1 id="clone-your-github-pages-repository">Clone Your GitHub Pages repository</h1>

<p>By convention, the GitHub Pages site for user <strong>username</strong> is hosted in a repo named <strong>username.github.io</strong>. For instance, the blog you’re reading is hosted at <a href="https://github.com/tlouarn/tlouarn.github.io">https://github.com/tlouarn/tlouarn.github.io</a>.</p>

<p>Clone your repo locally using:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/<span class="o">{</span>username<span class="o">}</span>/<span class="o">{</span>username<span class="o">}</span>.github.io
</code></pre></div></div>

<h1 id="add-a-docker-composeyml-file">Add a docker-compose.yml File</h1>

<p>At the root of your project, create a <code class="language-plaintext highlighter-rouge">docker-compose.yml</code> file. This file defines which containers to run.</p>

<p>Paste the following:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>version: <span class="s1">'2.4'</span>

services:
  jekyll:
    image: bretfisher/jekyll-serve
    volumes:
      - .:/site
    ports:
      - <span class="s1">'80:4000'</span>
</code></pre></div></div>

<p>This sets up a Jekyll service using the <strong>bretfisher/jekyll-serve</strong> image and maps port 4000 inside the container to port 80 on your machine. When the container starts, everything in the local project directory is accessible inside the container at <code class="language-plaintext highlighter-rouge">/site</code> (in particular, the generated website will be served from <code class="language-plaintext highlighter-rouge">/site/_site</code>).</p>

<h1 id="add-a-gemfile">Add a Gemfile</h1>

<p>A <strong>Gemfile</strong> is a plain-text manifest that tells <strong>Bundler</strong> (Ruby’s dependency manager) what libraries (called <em>gems</em>) your project requires and which versions to use. It ensures that anyone who clones the repository can install exactly the same dependencies, keeping the development and production environments in sync.</p>

<p>Create a Gemfile with the following content:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">source</span> <span class="s2">"https://rubygems.org"</span>

gem <span class="s1">'github-pages'</span>, group: :jekyll_plugins
</code></pre></div></div>

<p>This ensures your local Jekyll environment matches GitHub Pages exactly. The <strong>github-pages</strong> gem pins versions of Jekyll and all supported plugins so what you see locally is what you’ll get when GitHub builds your site.</p>

<h1 id="update-your-gitignore-optional-but-recommended">Update your .gitignore (optional but recommended)</h1>

<p>Since Docker will generate extra files (like <code class="language-plaintext highlighter-rouge">_site</code>), you may want to add them to your <code class="language-plaintext highlighter-rouge">.gitignore</code> file so they don’t clutter your commits. Example:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>_site/
</code></pre></div></div>

<h1 id="run-the-site-locally">Run the site locally</h1>

<p>From the project root, start Docker with:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker-compose up
</code></pre></div></div>

<p>This will spin up a Jekyll server inside Docker, generate your site into the <code class="language-plaintext highlighter-rouge">_site</code> folder and serve it at <a href="http://localhost/">http://localhost/</a>. The best part? <strong>Live reload</strong> is enabled, so changes you make to your files will instantly update in your browser.</p>

<hr />

<p>References:</p>

<ul>
  <li><a href="https://docs.docker.com/get-started/">https://docs.docker.com/get-started/</a></li>
  <li><a href="https://blog.nimblepros.com/blogs/github-pages-with-dev-containers/">https://blog.nimblepros.com/blogs/github-pages-with-dev-containers/</a></li>
  <li><a href="https://bjm.me.uk/blog/testing-github-pages-locally-docker/">https://bjm.me.uk/blog/testing-github-pages-locally-docker/</a></li>
</ul>]]></content><author><name>tlouarn</name></author><category term="docker" /><category term="jekyll" /><summary type="html"><![CDATA[If, like me, you are building a personal site or project page with GitHub Pages, you have probably wanted to preview it locally before pushing changes live. Luckily, with Docker and Jekyll, you can spin up a local version of your site in minutes, running in a clean, isolated container. Here is a step-by-step guide tested under Windows 11 Professional Edition.]]></summary></entry><entry><title type="html">Building a live order book using Python</title><link href="https://tlouarn.com/2025/05/03/building-a-live-order-book-using-python.html" rel="alternate" type="text/html" title="Building a live order book using Python" /><published>2025-05-03T00:00:00+00:00</published><updated>2025-05-03T00:00:00+00:00</updated><id>https://tlouarn.com/2025/05/03/building-a-live-order-book-using-python</id><content type="html" xml:base="https://tlouarn.com/2025/05/03/building-a-live-order-book-using-python.html"><![CDATA[<h1 id="introduction">Introduction</h1>

<p>This post examines design considerations for implementing a live order book GUI in Python using PySide6. <strong>PySide</strong> is the official Python port of the popular Qt framework. For the data source, we will use a free Bitcoin order book feed provided by <strong>Bitfinex</strong>.</p>

<h1 id="websockets">Websockets</h1>

<p><strong>WebSockets</strong> is a communication protocol that operates over a single TCP connection and allows real-time data exchange between a client and a server. Unlike traditional HTTP requests, which are one-way and require constant polling for updates, WebSockets provide a persistent connection where both the client and the server can send data at any time.</p>

<p>In Python, the most commonly used package for WebSocket communication is <code class="language-plaintext highlighter-rouge">websockets</code>. This package is an asyncio-based library that supports both client and server WebSocket implementations.</p>

<p>The Bitfinex API v2 gives access to a live Bitcoin order book via a WebSocket connection. The documentation of the <strong>book</strong> channel can be found <a href="https://docs.bitfinex.com/reference/ws-public-books">here</a>. Once connected to the WebSocket API, the client receives messages in the following order: first a snapshot of the current order book, then some updates to the order book (changes in prices and quantities of bids and asks). Once every 15 seconds, the client receives a heartbeat message to confirm that the connection is still open. It is therefore the client’s responsibility to maintain an internal representation of the order book and to update it accordingly with the messages received.</p>

<h1 id="design-decisions">Design decisions</h1>

<p>I have broken down the program into several key components:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">BitfinexHandler</code>: interacts with the Bitfinex WebSockets API</li>
  <li><code class="language-plaintext highlighter-rouge">OrderBookModel</code>: maintains an up-to-date internal representation of the order book</li>
  <li><code class="language-plaintext highlighter-rouge">MainWindow</code>: ties the handler and the model to the UI</li>
</ul>

<p>First thing first, we don’t want our UI to freeze while we are handling market data, therefore we will use asynchronous programming with the <strong>asyncio</strong> framework as well as Qt’s own <strong>signals</strong> mechanism. We showcase the use of signals by updating the status bar of the main window whenever the connection is (asynchronously) opened or closed by the handler.</p>

<p><code class="language-plaintext highlighter-rouge">BitfinexHandler</code> is our primary client for the Bitfinex Websockets API. We implement it as a subclass of <code class="language-plaintext highlighter-rouge">QObject</code> in order to be able to emit signals. When it opens or close a connection, <code class="language-plaintext highlighter-rouge">BitfinexHandler</code> emits a specific signal that can be captured by the main window. When listening to updates of the <strong>book</strong> channel for Bitcoin (tBTCUSD), it calls back a custom <code class="language-plaintext highlighter-rouge">handle_message</code> method from <code class="language-plaintext highlighter-rouge">MainWindow</code>.</p>

<p>We could choose to maintain our data model directly as it is represented (i.e. a 5x4 table), or we could maintain it in a dedicated structure and implement standard methods by which our view can represent it as a table. Since it is generally good practice to  separate data from UI, we choose the second option. To do so, instead of relying on a <code class="language-plaintext highlighter-rouge">QTableWidget</code> component, we choose to use a custom <code class="language-plaintext highlighter-rouge">QTableView</code> together with a custom <code class="language-plaintext highlighter-rouge">QAbstractTableModel</code>. This way, instead of directly updating the table cells, we update an internal model that is then translated by the view into a 5x4 table.</p>

<p>The main window controls the show. It builds the interface using a button, a table and a status bar. It initiates our client using its own <code class="language-plaintext highlighter-rouge">handle_message</code> method as a callback, meaning this method is called everytime the client receives a message. The message can either be informative (like a heartbeat) or market-related. In the latter case, the message would either be a 50-long list (25 limits on either side of bids and asks) or a 1-long list (update of a single limit). The <code class="language-plaintext highlighter-rouge">handle_message</code> method passes on the messages received from the handler into our order book model and notifies the view that the model has been updated.</p>

<p>Finally, we use <strong>qasync</strong> in order to integrate Qt’s own event loop with asyncio’s separate event loop.</p>

<h1 id="ui-considerations">UI considerations</h1>

<p>In terms of UI, we want the user to start and stop the connection with buttons. A button should always display an action rather than a status. We could imagine two buttons: <strong>Start</strong> and <strong>Stop</strong>. Since we do not want the user to start a system already started nor to stop a system already stopped, only one of these two buttons should be enabled at all times. In fact, we could probably use a single button which action changes depending on the state of the system. This is what we implemented using our own <code class="language-plaintext highlighter-rouge">ToggleButton</code> widget. One last subtlety: while the system is connecting or disconnecting, we temporarily disable the button and enable it again once the system is either fully connected or fully disconnected. This avoids clicking twice while the previous operation is still running.</p>

<p>Qt provides a default design for its components but we want some degree of customization linked to the type of application we are building and the type of data we are handling. Among the questions to be asked are: What font should be used? What font size is optimal? How much spacing inside the cells? Should we right-align all numbers? How many decimals should be displayed? How to remove double borders (cell borders and table borders)? Thankfully, the Qt framework is customizable via its own CSS so we have provided our custom components with their own style sheets. In order to not make <code class="language-plaintext highlighter-rouge">main_window.py</code> too big, we have placed the button and the table classes in their own files, still in the <code class="language-plaintext highlighter-rouge">views</code> folder.</p>

<h1 id="the-result">The result</h1>

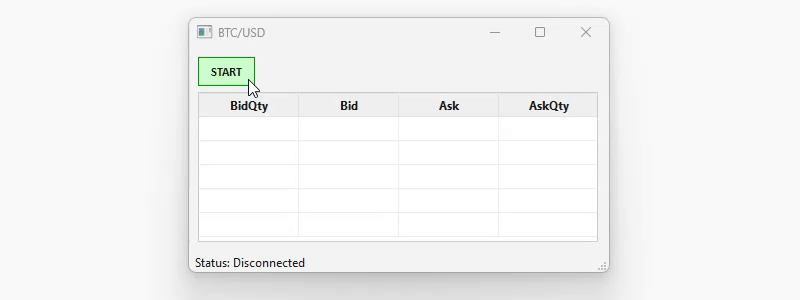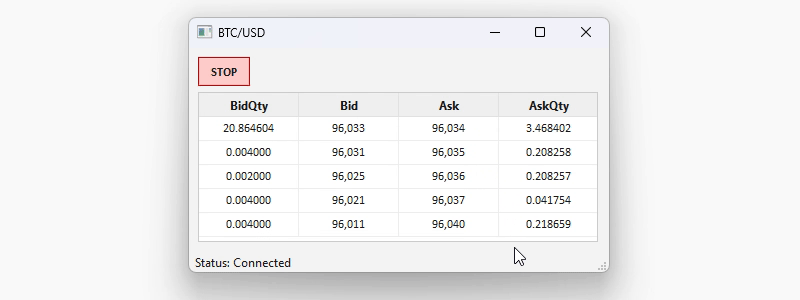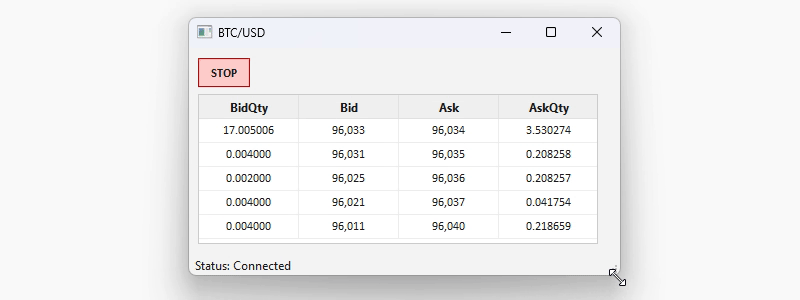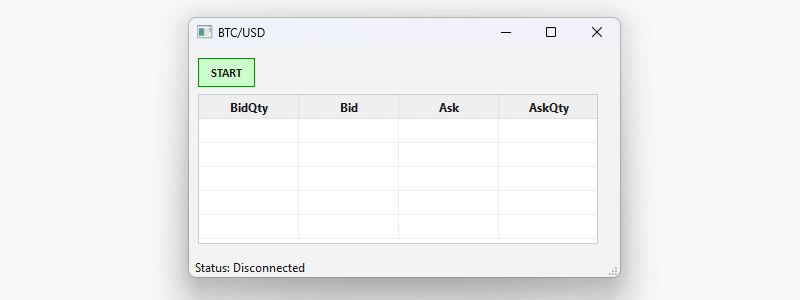
<p>The result is a responsive, asynchronous and (hopefully) good-looking UI that shows a live Bitcoin order book. The user can start and stop the feed with a toggle button. Most importantly, the interface remains fully responsive in any possible state of the WebSocket connection. This allows for instance the user to resize the window while, in the background, the client is connecting to the feed or the view is updating the table.</p>

<p><img src="/assets/images/tlouarn-building-a-live-order-book-using-python.gif" alt="Live order book using Python" /></p>

<p>The final project can be found on <a href="https://github.com/tlouarn/order-book/">my GitHub</a>.</p>]]></content><author><name>tlouarn</name></author><category term="python" /><category term="ui" /><summary type="html"><![CDATA[Introduction]]></summary></entry><entry><title type="html">Moving to GitHub Pages</title><link href="https://tlouarn.com/2025/02/23/moving-to-github-pages.html" rel="alternate" type="text/html" title="Moving to GitHub Pages" /><published>2025-02-23T00:00:00+00:00</published><updated>2025-02-23T00:00:00+00:00</updated><id>https://tlouarn.com/2025/02/23/moving-to-github-pages</id><content type="html" xml:base="https://tlouarn.com/2025/02/23/moving-to-github-pages.html"><![CDATA[<p>Over the years, I’ve experimented with various platforms and setups to host this blog: a WordPress site,   a custom Python MVC backend running on AWS Lambda, a Hugo static website, a <a href="/2023/07/12/hosting-ghost-on-aws-ec2.html">self-hosted Ghost instance</a> etc. However, rising costs eventually led me to migrate to GitHub Pages, which is free and does the job.</p>

<h1 id="what-is-github-pages">What is GitHub Pages</h1>

<p><a href="https://docs.github.com/en/pages">GitHub Pages</a> is a free service provided by GitHub that allows you to host a static website directly from one of your GitHub repositories. It is based on a static site generator named <a href="https://jekyllrb.com/">Jekyll</a>, which serves the content located in a special repository named <code class="language-plaintext highlighter-rouge">{username}.github.io</code> (each GitHub user can create one such special repository). Thanks to GitHub Actions, each commit to this specific repository triggers a build of the static website. In other words, once the setup is in place, all you need to do is push a new post to the repository for your website to update.</p>

<h1 id="getting-started">Getting started</h1>

<p>Create a new repository named <code class="language-plaintext highlighter-rouge">{username}.github.io</code></p>

<p>Add 2 files:</p>
<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>_config.yml
main.md
</code></pre></div></div>

<p>Let’s now setup GitHub Actions for this repository. A GitHub Action is hosted by GitHub on a Linux instance and can be parameterized using YAML files.</p>

<p>Go to the repository settings. Under <code class="language-plaintext highlighter-rouge">Code and automation</code>, select <code class="language-plaintext highlighter-rouge">Pages</code>. Under <code class="language-plaintext highlighter-rouge">Build and deployment</code>, select <code class="language-plaintext highlighter-rouge">Deploy from a branch</code> and choose <code class="language-plaintext highlighter-rouge">main</code>. From now on, each new push to the main branch will trigger a website refresh. The generated html is stored by Github in a special <code class="language-plaintext highlighter-rouge">_site</code> folder that can’t be accessed from the repo.</p>

<p>The website is now publicly available at <code class="language-plaintext highlighter-rouge">https://{username}.github.io</code>, but it is also possible to configure a custom domain name. The process involves two steps:</p>
<ol>
  <li>securing the domain name within GitHub to prevent domain takeover (see details <a href="https://docs.github.com/en/pages/configuring-a-custom-domain-for-your-github-pages-site/verifying-your-custom-domain-for-github-pages">here</a>)</li>
  <li>configuring the apex domain at your DNS provider</li>
</ol>

<h1 id="website-structure">Website structure</h1>

<p>In the website repository, the folder structure looks like the below:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># The GitHub Actions</span>
.github/workflows
    jekyll-gh-pages.yml

<span class="c"># A .gitignore is always welcome</span>
.gitignore

<span class="c"># The _config.yml file contains all the parameters for Jekyll</span>
_config.yml

<span class="c"># Posts are simple MarkDown files located in the _posts directory</span>
_posts
    2020-01-01-example-post.md
    2020-02-01-example-post-2.md
    ...

<span class="c"># Images are contained within the assets/images directory</span>
assets/images
    image1.jpeg
    image2.jpeg
    ...

<span class="c"># The main pages are located directly at the root (they can be either HTML or MarkDown)</span>
404.html
archive.html
index.md

<span class="c"># A CNAME file can be required for domain name verification</span>
CNAME
</code></pre></div></div>

<p>You can view the structure of this blog at <a href="https://github.com/tlouarn/tlouarn.github.io">https://github.com/tlouarn/tlouarn.github.io</a>.</p>

<h1 id="some-customization-tips">Some customization tips</h1>

<p><strong>How to add a table of contents:</strong></p>
<ul>
  <li>add <code class="language-plaintext highlighter-rouge">markdown: kramdown</code> to <code class="language-plaintext highlighter-rouge">_config.yml</code></li>
  <li>on each post, add a dummy ordered/unordered list item followed by <code class="language-plaintext highlighter-rouge">{:toc}</code></li>
</ul>

<p>For instance, I use:</p>
<div class="language-markdown highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="gs">**Table of Contents:**</span>
<span class="p">*</span> 
{:toc}
</code></pre></div></div>

<p>This will generate an unordered table of contents.</p>

<p><strong>How to add LaTeX equations</strong></p>

<p>I use <a href="https://katex.org/">KaTeX</a> via a simple JavaScript insert in my header:</p>

<div class="language-html highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c">&lt;!-- KaTex --&gt;</span>
<span class="nt">&lt;link</span> <span class="na">async</span> <span class="na">rel=</span><span class="s">"stylesheet"</span> <span class="na">href=</span><span class="s">"https://cdn.jsdelivr.net/npm/katex@0.16.0/dist/katex.min.css"</span> <span class="na">crossorigin=</span><span class="s">"anonymous"</span><span class="nt">&gt;</span>
<span class="nt">&lt;script </span><span class="na">defer</span> <span class="na">src=</span><span class="s">"https://cdn.jsdelivr.net/npm/katex@0.16.0/dist/katex.min.js"</span> <span class="na">crossorigin=</span><span class="s">"anonymous"</span><span class="nt">&gt;&lt;/script&gt;</span>
<span class="nt">&lt;script </span><span class="na">defer</span> <span class="na">src=</span><span class="s">"https://cdn.jsdelivr.net/npm/katex@0.16.0/dist/contrib/auto-render.min.js"</span> <span class="na">crossorigin=</span><span class="s">"anonymous"</span> <span class="na">onload=</span><span class="s">"renderMathInElement(document.body);"</span><span class="nt">&gt;&lt;/script&gt;</span>
</code></pre></div></div>

<p>KaTeX expressions must be escaped using <code class="language-plaintext highlighter-rouge">\\[</code> and <code class="language-plaintext highlighter-rouge">\\]</code>. Here is how to write a simple equation:</p>

<pre><code class="language-code">\\[ C - P= D \cdot (F - K) \\]
</code></pre>
<p>and how it is rendered:</p>

<p>\[ C - P= D \cdot (F - K) \]</p>

<p><strong>How to customize CSS</strong></p>

<p>GitHub Pages currently runs on minima v2.5.1. In order to overwrite or add custom css, the easiest way is to create <code class="language-plaintext highlighter-rouge">assets/main.scss</code> and import the minima style inside, then overwrite it.</p>

<div class="language-scss highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nt">---</span>
<span class="nn">#</span> <span class="nt">Only</span> <span class="nt">the</span> <span class="nt">main</span> <span class="nt">Sass</span> <span class="nt">file</span> <span class="nt">needs</span> <span class="nt">front</span> <span class="nt">matter</span> <span class="o">(</span><span class="nt">the</span> <span class="nt">dashes</span> <span class="nt">are</span> <span class="nt">enough</span><span class="o">)</span>
<span class="nt">---</span>

<span class="o">@</span><span class="nt">import</span> <span class="s2">"minima"</span><span class="p">;</span>

<span class="nt">body</span> <span class="p">{</span>
    <span class="nl">font</span><span class="p">:</span> <span class="n">Helvetica</span><span class="o">,</span><span class="n">Arial</span><span class="o">,</span><span class="nb">sans-serif</span><span class="p">;</span>
    <span class="nl">letter-spacing</span><span class="p">:</span>  <span class="m">-1px</span><span class="p">;</span>
<span class="p">}</span>
</code></pre></div></div>

<p>A better way is to fork the <a href="https://github.com/jekyll/minima">minima theme</a> into a custom repo (I chose <code class="language-plaintext highlighter-rouge">tlouarn/minima</code>), strip all the unnecessary files and customize it by overwriting styles in <code class="language-plaintext highlighter-rouge">_sass/minima/custom-variables.scss</code> and <code class="language-plaintext highlighter-rouge">_sass/minima/custom-styles.scss</code>. Back to the main repo, add the following line to <code class="language-plaintext highlighter-rouge">_config.yml</code>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">remote_theme</span><span class="pi">:</span> <span class="s">tlouarn/minima</span>
</code></pre></div></div>

<p>This way, content and presentation are cleanly separated. Also, the actual theme is now frozen (in case GitHub chooses to update the default theme at a later stage).</p>

<p><strong>How to add images</strong></p>

<p>Image files need to be uploaded into <code class="language-plaintext highlighter-rouge">assets/images</code> and can be referenced like so:</p>

<div class="language-markdown highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">![</span><span class="nv">Image</span><span class="p">](</span><span class="sx">/assets/images/image.jpg</span><span class="p">)</span>
</code></pre></div></div>

<p><strong>How to link other posts</strong></p>

<p>To create a hyperlink to another post named “2020-01-01-example-post.md”, enter the below:</p>

<div class="language-markdown highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">[</span><span class="nv">link text</span><span class="p">](</span><span class="sx">{%</span> post_url 2020-01-01-example-post %})
</code></pre></div></div>]]></content><author><name>tlouarn</name></author><category term="howto" /><category term="web" /><summary type="html"><![CDATA[Over the years, I’ve experimented with various platforms and setups to host this blog: a WordPress site, a custom Python MVC backend running on AWS Lambda, a Hugo static website, a self-hosted Ghost instance etc. However, rising costs eventually led me to migrate to GitHub Pages, which is free and does the job.]]></summary></entry><entry><title type="html">Combinatorics 101</title><link href="https://tlouarn.com/2023/08/07/combinatorics-101.html" rel="alternate" type="text/html" title="Combinatorics 101" /><published>2023-08-07T00:00:00+00:00</published><updated>2023-08-07T00:00:00+00:00</updated><id>https://tlouarn.com/2023/08/07/combinatorics-101</id><content type="html" xml:base="https://tlouarn.com/2023/08/07/combinatorics-101.html"><![CDATA[<p>A <strong>permutation</strong> is an arrangement where order matters. A <strong>combination</strong> is an arrangement where order does not. There are fewer combinations than permutations.</p>

<p>Formulas to count the arrangements of \(k\) elements among \(n\):</p>

<table>
  <thead>
    <tr>
      <th>Type</th>
      <th>Repetitions</th>
      <th>Formula</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Permutation</td>
      <td>Yes</td>
      <td>\( n^k \)</td>
    </tr>
    <tr>
      <td>Permutation</td>
      <td>No</td>
      <td>\( \frac{n!}{(n-k)!} \)</td>
    </tr>
    <tr>
      <td>Combination</td>
      <td>No</td>
      <td>\( \frac{n!}{k! \times (n-k)!} \)</td>
    </tr>
    <tr>
      <td>Combination</td>
      <td>Yes</td>
      <td>\( \frac{(n+k-1)!}{k! \cdot (n-1)!} \)</td>
    </tr>
  </tbody>
</table>

<h1 id="permutation-with-repetition">Permutation with repetition</h1>

<p>We have a set of \(n\) elements, we build an ordered list of \(k\) elements chosen among the set with repetitions allowed. At each of the \(k\) draws, we can choose among \(n\) possibilities. The resulting number of permutations is:
\[ n^k \]</p>

<h1 id="permutation-without-repetition">Permutation without repetition</h1>

<p>We have a set of \(n\) elements, we build an ordered list of \(k\) elements chosen among the set with no repetition allowed. For the first draw, we can choose among \(n\) elements. For the second draw, we can choose among \((n - 1)\) elements, etc. The resulting number of permutations is:
\[ P(n, k) = \frac{n!}{ (n-k)!} \]</p>

<h1 id="combination-without-repetition">Combination without repetition</h1>

<p>This is the binomial coefficient. It’s a combination so the order does not matter. It can be expressed as a permutation altered t
\[ {n \choose k} = C(n, k) = \frac{P(n, k)}{k!} = \frac{ n! }{k! \times (n-k)!} \]</p>

<h1 id="combination-with-repetition">Combination with repetition</h1>

<p>This is a tricky one. 
\[ { n+k-1 \choose k } = \frac{(n+k-1)!}{k! \times (n-1)!} \]</p>

<h1 id="examples">Examples</h1>

<details>
    <summary>Number of ways the letters A, B and C can be arranged with repetitions</summary>
    <p>$$3^3 = 27$$</p>
</details>

<details>
    <summary>Number of ways the letters A, B and C can be arranged without repetition</summary>
    <p>$$3! = 6$$</p>
</details>

<details>
    <summary>Probability of 3 heads in 5 coin flips</summary>
    <p>$$10/32$$</p>
</details>

<details>
    <summary>How many ways can first and second place be awarded to 10 people?</summary>
    <p>Number of permutations without repetition of 2 in 10: $$\frac{10!}{(10 - 2)!} = 10 \times 9 = 90$$</p>
</details>

<details>
    <summary>How many different ways can 3 red, 4 yellow and 2 blue bulbs be arranged in a string of Christmas tree lights with 9 sockets?</summary>
    <p> We assume all bulbs are individually identified: there are a total of $$9!$$ permutations. We then divide by the number of permutations within each group of bulbs: $$\frac{9!}{3! \times 4! \times 2!} = 1260$$</p>
</details>

<details>
    <summary>How many different sets of 4 letters can be selected from the alphabet?</summary>
    <p>We want the number of combinations without repetitions: $${26 \choose 4} = \frac{26!}{4! \times (26-4)!} = 14950$$</p>
</details>

<details>
    <summary>How many cups of ice-cream can we build by choosing 3 scoops among 5 flavors?</summary>
    <p> This is a combination with repetition. The order of the scoops does not matter, and we can have several times the same flavor. The solution is: $$\frac{(5+3-1)!}{3! \times (5-1)!} = 35$$</p>
</details>

<hr />

<p>References:</p>
<ul>
  <li><a href="https://betterexplained.com/articles/easy-permutations-and-combinations/">https://betterexplained.com/articles/easy-permutations-and-combinations/</a></li>
  <li><a href="https://www.intmath.com/counting-probability/3-permutations.php">https://www.intmath.com/counting-probability/3-permutations.php</a></li>
  <li><a href="https://www.mathsisfun.com/combinatorics/combinations-permutations.html">https://www.mathsisfun.com/combinatorics/combinations-permutations.html</a></li>
</ul>]]></content><author><name>tlouarn</name></author><category term="probabilities" /><summary type="html"><![CDATA[A permutation is an arrangement where order matters. A combination is an arrangement where order does not. There are fewer combinations than permutations.]]></summary></entry><entry><title type="html">Linux 101</title><link href="https://tlouarn.com/2023/07/22/linux-101.html" rel="alternate" type="text/html" title="Linux 101" /><published>2023-07-22T00:00:00+00:00</published><updated>2023-07-22T00:00:00+00:00</updated><id>https://tlouarn.com/2023/07/22/linux-101</id><content type="html" xml:base="https://tlouarn.com/2023/07/22/linux-101.html"><![CDATA[<p><strong>Linux</strong> is an open-source operating system. Its core components are a boot loader, a kernel, basic services including a shell, and a package manager. Linux can also come with a display manager and some applications (like LibreOffice or GIMP).</p>

<p>There are tons of different Linux distributions, but most of them belong to a specific <strong>family</strong>. The three main families of distributions are:</p>

<p><img src="/assets/images/tlouarn-linux-101-linux-families.png" alt="The three main families of Linux distributions" /></p>

<p>Since I use Ubuntu on my WSL and Amazon EC2, and Ubuntu belongs to the Debian family, I will only write down useful commands and tools from the Debian family.</p>

<p>Table of contents:</p>
<ul id="markdown-toc">
  <li><a href="#the-file-system" id="markdown-toc-the-file-system">The file system</a></li>
  <li><a href="#the-command-line" id="markdown-toc-the-command-line">The command line</a></li>
  <li><a href="#navigating-the-directory" id="markdown-toc-navigating-the-directory">Navigating the directory</a></li>
  <li><a href="#manipulating-files-and-directories" id="markdown-toc-manipulating-files-and-directories">Manipulating files and directories</a></li>
  <li><a href="#the-package-manager" id="markdown-toc-the-package-manager">The package manager</a></li>
  <li><a href="#editing-files" id="markdown-toc-editing-files">Editing files</a></li>
  <li><a href="#user-management" id="markdown-toc-user-management">User management</a></li>
  <li><a href="#environment-variables" id="markdown-toc-environment-variables">Environment variables</a></li>
  <li><a href="#manipulating-files" id="markdown-toc-manipulating-files">Manipulating files</a></li>
  <li><a href="#streams-and-pipes" id="markdown-toc-streams-and-pipes">Streams and pipes</a></li>
  <li><a href="#processes" id="markdown-toc-processes">Processes</a></li>
  <li><a href="#cron" id="markdown-toc-cron">Cron</a></li>
  <li><a href="#networks" id="markdown-toc-networks">Networks</a></li>
</ul>

<h1 id="the-file-system">The file system</h1>

<p>The file system works as a <a href="/graph-theory-101">tree</a>. Unlike Windows where there can be multiple roots like <code class="language-plaintext highlighter-rouge">C:\</code> and <code class="language-plaintext highlighter-rouge">D:\</code>, Linux only has one root and it is accessible via <code class="language-plaintext highlighter-rouge">/</code>. All other files, directories and partitions are located under the root. In particular, multiple drives are mounted under <code class="language-plaintext highlighter-rouge">/mnt</code>.</p>

<p>The Filesystem Hierarchy Standard (FHS) describes the main top-level directories located just under the root:</p>

<table>
  <thead>
    <tr>
      <th>name</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>/bin</strong></td>
      <td>user binaries</td>
    </tr>
    <tr>
      <td><strong>/boot</strong></td>
      <td>boot loader files</td>
    </tr>
    <tr>
      <td><strong>/dev</strong></td>
      <td>device files</td>
    </tr>
    <tr>
      <td><strong>/etc</strong></td>
      <td>configuration files</td>
    </tr>
    <tr>
      <td><strong>/home</strong></td>
      <td>home directories</td>
    </tr>
    <tr>
      <td><strong>/lib</strong></td>
      <td>system libraries</td>
    </tr>
    <tr>
      <td><strong>/media</strong></td>
      <td>removable devices</td>
    </tr>
    <tr>
      <td><strong>/mnt</strong></td>
      <td>mount directory</td>
    </tr>
    <tr>
      <td><strong>/opt</strong></td>
      <td>optional applications</td>
    </tr>
    <tr>
      <td><strong>/proc</strong></td>
      <td>process information</td>
    </tr>
    <tr>
      <td><strong>/root</strong></td>
      <td>home directory for the root user</td>
    </tr>
    <tr>
      <td><strong>/sbin</strong></td>
      <td>system binaries</td>
    </tr>
    <tr>
      <td><strong>/srv</strong></td>
      <td>service data</td>
    </tr>
    <tr>
      <td><strong>/tmp</strong></td>
      <td>temporary files</td>
    </tr>
    <tr>
      <td><strong>/usr</strong></td>
      <td>multi-user programs</td>
    </tr>
    <tr>
      <td><strong>/var</strong></td>
      <td>variable files</td>
    </tr>
  </tbody>
</table>

<p>Notes:</p>
<ul>
  <li>The file system is <strong>case-sensitive</strong></li>
  <li>Each user has a directory under <strong>/home</strong> named after him</li>
  <li><strong>/proc</strong> contains virtual files that only exist in memory</li>
  <li><strong>/etc</strong> contains system configuration files (only the root user can edit)</li>
  <li><strong>/lib</strong> contains dynamically loaded libraries</li>
</ul>

<h1 id="the-command-line">The command line</h1>

<p>The command line is a text-based interface where users can interact with the operating system by typing commands. The basic structure of a command is:</p>

<pre><code class="language-cmd">command [flags] [arguments]
</code></pre>

<p>The <strong>command</strong> is the program or action to run. The <strong>flags</strong> are optional and modify the behavior of the command if needed. The <strong>arguments</strong> are the input of the command. For example, typing <code class="language-plaintext highlighter-rouge">df -Th /</code> displays the amount of available <strong>disk space</strong> for the root filesystem along with their type and human-readable numbers. We can break down this instruction as follows:</p>

<table>
  <thead>
    <tr>
      <th>part</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">df</code></td>
      <td>disk free</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">-T</code></td>
      <td>displays the filesystem type (e.g. ext4)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">-h</code></td>
      <td>show the sizes in human-readable format (KB, MB, GB)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">/</code></td>
      <td>applies the command and flags to the root</td>
    </tr>
  </tbody>
</table>

<h1 id="navigating-the-directory">Navigating the directory</h1>

<p>Below are some basic commands to navigate the directory and manipulate files.</p>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pwd</code></td>
      <td>print working directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cd</code></td>
      <td>change directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cd ~</code></td>
      <td>change to your home directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cd ..</code></td>
      <td>change to parent directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cd -</code></td>
      <td>change to previous directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cd /</code></td>
      <td>change to the root directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ls</code></td>
      <td>list the contents of the directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">tree</code></td>
      <td>display a tree view of the filesystem</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pushd</code></td>
      <td>push the current directory onto a stack for later use and move to the specified directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">popd</code></td>
      <td>change to the top directory off the stack</td>
    </tr>
  </tbody>
</table>

<p>Some flags often used with the <code class="language-plaintext highlighter-rouge">ls</code> command:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">ls -a</code> lists <strong>all</strong> contents including hidden files and directories</li>
  <li><code class="language-plaintext highlighter-rouge">ls -i</code> includes the <strong>inode</strong> of each file</li>
  <li><code class="language-plaintext highlighter-rouge">ls -h</code> displays files sizes in a <strong>human</strong>-readable format</li>
  <li><code class="language-plaintext highlighter-rouge">ls -l</code> shows more information</li>
</ul>

<p>Flags can be combined: <code class="language-plaintext highlighter-rouge">ls -aihl</code> does all of the above at once. <code class="language-plaintext highlighter-rouge">ls</code> also works with Globbing patterns, such as <code class="language-plaintext highlighter-rouge">ls *.txt</code> to list all files with a txt extension.</p>

<p>In order to get help on any command, type <code class="language-plaintext highlighter-rouge">man [command]</code> (which stands for “manual”). For instance, to get help on <code class="language-plaintext highlighter-rouge">find</code>, type <code class="language-plaintext highlighter-rouge">man find</code>. This proves useful when looking for specific flags. To interrupt a command, type <code class="language-plaintext highlighter-rouge">Ctrl + C</code>. To clear the command line, type <code class="language-plaintext highlighter-rouge">Ctrl + L</code>.</p>

<h1 id="manipulating-files-and-directories">Manipulating files and directories</h1>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cat</code></td>
      <td>print content onto the standard output stream</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">head</code></td>
      <td>print the first 10 lines of a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">tail</code></td>
      <td>print the last 10 lines of a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">less</code></td>
      <td>print a file one page at a time</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">touch</code></td>
      <td>create a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">mv</code></td>
      <td>rename a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">rm</code></td>
      <td>remove a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">rm -rf</code></td>
      <td>empty a directory recursively</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">rmdir</code></td>
      <td>remove a directory (only works when the directory is empty)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">mkdir</code></td>
      <td>create a directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ln</code></td>
      <td>create a symbolic link</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">diff</code></td>
      <td>compare files and directories</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">file</code></td>
      <td>give the real nature of a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cp</code></td>
      <td>copy files on the local machine</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">patch</code></td>
      <td>apply changes to a file (changes are contained in patchfiles)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">which</code></td>
      <td>locate a program</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">whereis</code></td>
      <td>locate searching in a broader range</td>
    </tr>
  </tbody>
</table>

<p>Note: most applications open the file rather than rely on extensions. Extensions are more useful for the user than for the system. Hence the <code class="language-plaintext highlighter-rouge">file</code> command.</p>

<h1 id="the-package-manager">The package manager</h1>

<p><strong>APT</strong> (Advanced Package Tool) is the default package manager on Debian. It is made of two components which are <code class="language-plaintext highlighter-rouge">apt-get</code> (high-level package manager used for dependency resolution) and <code class="language-plaintext highlighter-rouge">dpkg</code> (low-level package manager working under the hood). Most of the time we use <code class="language-plaintext highlighter-rouge">apt-get</code>.</p>

<p>Example commands:</p>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">apt-get upgrade</code></td>
      <td>upgrade all installed packages to their latest version</td>
    </tr>
    <tr>
      <td><code>dpkg --list &#124; grep zip</code></td>
      <td>show all installed packages which name contains “zip”</td>
    </tr>
  </tbody>
</table>

<h1 id="editing-files">Editing files</h1>

<p>On the command-line, we can use Nano or Vi.</p>

<p>From the shell, let’s add “Hello World” to <strong>file1</strong>, then print the contents of <strong>file1</strong> to the command line:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$ </span><span class="nb">echo</span> <span class="s2">"Hello World"</span> <span class="o">&gt;</span> file1
<span class="nv">$ </span><span class="nb">cat </span>file1
Hello World
</code></pre></div></div>

<p>To open the file in Nano, type <code class="language-plaintext highlighter-rouge">nano my_file</code>.</p>

<h1 id="user-management">User management</h1>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">id</code></td>
      <td>information about the current user</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">id [username]</code></td>
      <td>information about [username]</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">sudo useradd [username]</code></td>
      <td>add a new user named [username]</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">sudo userdel [username]</code></td>
      <td>delete user [username]</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">sudo userdel [username] -r</code></td>
      <td>fully delete [username] including his <strong>home</strong> directory</td>
    </tr>
  </tbody>
</table>

<p>Each user has a unique <strong>id</strong>. Groups gather users with common access rights and privileges. Normal users start at <strong>1000</strong>. All users are created with at least one group which id is equal to their uid.</p>

<table>
  <thead>
    <tr>
      <th>file</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>/etc/group</strong></td>
      <td>list of groups</td>
    </tr>
    <tr>
      <td><strong>/etc/passwd</strong></td>
      <td>list of users</td>
    </tr>
  </tbody>
</table>

<p>The <strong>/etc/passwd</strong> file is organized as follows:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>username:x:UID:GID:comment:home_directory:shell
</code></pre></div></div>

<p>How to search <strong>/etc/passwd</strong> for a specific user (here for user “root”):</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$ </span><span class="nb">grep </span>root /etc/passwd
root:x:0:0:root:/root:/bin/bash
</code></pre></div></div>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">useradd</code></td>
      <td>add a user directory under <strong>/home</strong> and add a line to  <strong>/etc/passwd</strong></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">userdel</code></td>
      <td>delete a user but leave the home directory unless <code class="language-plaintext highlighter-rouge">userdel -r</code></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">groupadd</code></td>
      <td>create a new group on the system</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">groupdel</code></td>
      <td>delete an existing group from the system</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">whoami</code></td>
      <td>display the current logged-in user name</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">su</code></td>
      <td>switch user : launch a new shell running as another user</td>
    </tr>
  </tbody>
</table>

<p>It is bad practice to use <code class="language-plaintext highlighter-rouge">su</code> to switch to root account. Instead, better use <code class="language-plaintext highlighter-rouge">sudo</code> on a user. This way, <strong>sudo</strong> privileges are granted to a specific user but only last for a specific command.</p>

<p>Every file is associated with a user and a group</p>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">chown</code></td>
      <td>change user ownership of a file or directory</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">chgrp</code></td>
      <td>change group ownership</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">chmod</code></td>
      <td>change the permissions on the file for <strong>owner</strong>, <strong>group</strong> and <strong>other</strong></td>
    </tr>
  </tbody>
</table>

<p><img src="/assets/images/tlouarn-linux-101-chmod.drawio.svg" alt="Illustration of chmod" /></p>

<h1 id="environment-variables">Environment variables</h1>

<p><strong>Environment variables</strong> are specific variables used by the shell.</p>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">env</code></td>
      <td>Print current environment variable to the shell</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">env &amp;#124; head</code></td>
      <td>Only print the first 10 variables</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">echo $SHELL</code></td>
      <td>Print the environment variable named <strong>SHELL</strong></td>
    </tr>
  </tbody>
</table>

<p><strong>PS1</strong> customize your prompt</p>

<p><strong>SHELL</strong> default shell for the current user, usually <strong>bash</strong></p>

<p>bash:
<code class="language-plaintext highlighter-rouge">history</code> history of commands entered</p>

<p><code class="language-plaintext highlighter-rouge">history | tail</code> show last 10</p>

<p>otherwise navigate using up/down arrow keys</p>

<p>Ctrl+R: search in history of past commands</p>

<p>Tab: autocomplete</p>

<h1 id="manipulating-files">Manipulating files</h1>

<p><code class="language-plaintext highlighter-rouge">cat</code> short for <strong>concatenate</strong></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ cat readme.txt
</code></pre></div></div>

<p>main purpose is to concatenate multiple files together</p>

<p>Some files are very large. Opening the file in an editor may consume too much memory. Using <code class="language-plaintext highlighter-rouge">less</code> allows to load page by page, not saturating the memory along with <code class="language-plaintext highlighter-rouge">head</code> and <code class="language-plaintext highlighter-rouge">tail</code>.</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$ </span><span class="nb">tail</span> <span class="nt">-15</span> somefile.log
<span class="nv">$ </span><span class="nb">tail</span> <span class="nt">-f</span> somefile.log
</code></pre></div></div>
<p><code class="language-plaintext highlighter-rouge">tail -f</code> continuously monitors new lines in the log file and displays them in stdout</p>

<p>Text utilities</p>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cat</code></td>
      <td>Concatenate files (can also read and print files)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">less</code></td>
      <td>Print the contents of a file in the shell page by page</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">head</code></td>
      <td>Show the first 10 lines of a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">tail</code></td>
      <td>Show the last 10 lines of a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">sed</code></td>
      <td>Edit data streams (filter and perform substitutions)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">awk</code></td>
      <td>Pattern scanning and processing</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">sort</code></td>
      <td>Sort text files and output streams</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">uniq</code></td>
      <td>Remove duplicate consecutive lines</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">paste</code></td>
      <td>Combine fields from different files</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">join</code></td>
      <td>Enhanced version of paste</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">split</code></td>
      <td>Break up large files into equal segments</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">wc</code></td>
      <td>Display the number of lines and words in a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cut</code></td>
      <td>Cut sections in each line of a file</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">grep</code></td>
      <td>Search text files and input streams (works with regex)</td>
    </tr>
  </tbody>
</table>

<h1 id="streams-and-pipes">Streams and pipes</h1>

<p><strong>Standard streams</strong> are communication channels between a computer program and its environment. When we launch a Linux command, three data streams are created:</p>

<ul>
  <li><strong>stdin</strong>: standard input</li>
  <li><strong>stdout</strong>: standard output</li>
  <li><strong>stderr</strong>: standard error</li>
</ul>

<p>When a command is executed via a shell, the streams are connected to the terminal on which the shell is running.</p>

<p>Streams can be directed and changed using <code class="language-plaintext highlighter-rouge">&gt;</code> and <code class="language-plaintext highlighter-rouge">&lt;</code>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$ </span>do_something &lt; input_file
<span class="nv">$ </span>do_something <span class="o">&gt;</span> output_file
<span class="nv">$ </span>do_something 2&gt; output_file
</code></pre></div></div>

<p>Programs can be chained together, where the <strong>stdout</strong> of the previous program is the <strong>stdin</strong> of the next:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$ </span>command_1 | command_2 | command_3
</code></pre></div></div>

<p>When several commands are chained together, each command does not have to wait for the previous command to finish before starting.</p>

<p>Searching for files:</p>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">locate</code></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">grep</code></td>
      <td>filter</td>
    </tr>
    <tr>
      <td><code>locate zip | grep bin</code></td>
      <td>print all files containing both “zip” and “bin”</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">find</code></td>
      <td> </td>
    </tr>
  </tbody>
</table>

<h1 id="processes">Processes</h1>

<p>Some clarification around the terminology:</p>

<ul>
  <li>a <strong>program</strong> is an executable sequence of instructions</li>
  <li>a <strong>process</strong> is the running instance of a program</li>
  <li>a <strong>thread</strong> is a lightweight process</li>
  <li>a <strong>service</strong> is process running in the background</li>
</ul>

<p>A process can run one or several threads, and can also run other processes.</p>

<p>There are two main commands to monitor processes:</p>

<table>
  <thead>
    <tr>
      <th>command</th>
      <th>description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ps</code></td>
      <td>reports a snapshot of current processes</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">top</code></td>
      <td>task manager that displays information about CPU and memory utilization (auto-refresh)</td>
    </tr>
  </tbody>
</table>

<p>A process can be defined by:</p>
<ul>
  <li>ID type</li>
  <li>Description</li>
  <li>Process ID (PID)</li>
  <li>Unique Process ID number</li>
  <li>Parent Process ID (PPID)</li>
  <li>PID of the parent process</li>
  <li>Thread ID (TID)</li>
  <li>Thread ID number</li>
</ul>

<p>For single-threaded processes, TID=PID. For multi-threaded processes, each thread shares the same PID but has a unique TID. To terminate a process: <code class="language-plaintext highlighter-rouge">kill -SIGKILL &lt;pid&gt;</code>. You can only terminate your own processes (unless you are root). Processes have priorities (their <code class="language-plaintext highlighter-rouge">nice</code> value, the lower the higher the priority). The “niceness” of a process is its priority. You can can change the niceness of a process from the CLI via <code class="language-plaintext highlighter-rouge">renice</code> command.</p>

<h1 id="cron">Cron</h1>

<p><strong>Cron</strong> makes it possible to launch background jobs at specific times.</p>

<p>We can schedule tasks by editing the <strong>crontab</strong> file (for <strong>cron table</strong>). We can access the crontab file by typing `crontab -e` (“crontab edit”). There are both system-wide and user-specific crontab files.</p>

<p>Cron instructions follow a specific format made of 6 fields:</p>

<table>
  <thead>
    <tr>
      <th>Field</th>
      <th>Description</th>
      <th>values</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>MIN</td>
      <td>Minutes</td>
      <td>0 to 59</td>
    </tr>
    <tr>
      <td>HOUR</td>
      <td>Hours</td>
      <td>0 to 23</td>
    </tr>
    <tr>
      <td>DOM</td>
      <td>Day Of Month</td>
      <td>1 to 31</td>
    </tr>
    <tr>
      <td>MON</td>
      <td>Month</td>
      <td>1 to 12</td>
    </tr>
    <tr>
      <td>DOW</td>
      <td>Day of Week</td>
      <td>0 to 6 (0 = Sunday)</td>
    </tr>
    <tr>
      <td>CMD</td>
      <td>Command</td>
      <td>Any command to be executed</td>
    </tr>
  </tbody>
</table>

<p>Example of cron schedule expression to run <code class="language-plaintext highlighter-rouge">script.sh</code> everyday at 1AM:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>0 1 <span class="k">*</span> <span class="k">*</span> <span class="k">*</span> /path/to/my/script.sh
</code></pre></div></div>

<h1 id="networks">Networks</h1>

<p>A network is a group of computers connected together via communication channels. Each device has an <strong>IP</strong> address (unique logical network address). A <strong>DNS</strong> converts a hostname into an IP address.</p>

<p>An IPv4 address is dividend into 4 bytes:</p>
<ul>
  <li>class A network address: first octet as Net ID, other 3 as Host ID max 126 class A. Classes A go from <code class="language-plaintext highlighter-rouge">1.0.0.0</code> to <code class="language-plaintext highlighter-rouge">127.255.255.255</code> (i.e. 16.7m unique hosts)</li>
  <li>classes B and C were added later:
class b: 2 bits 65k unique hosts
class c network addresses: first 3 octets as NET ID, last as host ID 2.1m available. Classes C go from <code class="language-plaintext highlighter-rouge">192.0.0.0</code> to <code class="language-plaintext highlighter-rouge">223.255.255.255</code></li>
</ul>

<p>Home network only has 1 IP address. Within the network, you can assign IPs to connected devices either statically or dynamically (DHCP).</p>

<p><strong>NAT</strong> = Network Address Translation, allows to share 1 IP address among many locally connected computers, each of which has a unique address only seen on the local network. In a home network, the router acts as a NAT.</p>

<p>Important files:</p>

<table>
  <thead>
    <tr>
      <th>File</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>/etc/resolv.conf</strong></td>
      <td> </td>
    </tr>
    <tr>
      <td><strong>/etc/hosts</strong></td>
      <td> </td>
    </tr>
    <tr>
      <td><strong>/etc/network</strong></td>
      <td> </td>
    </tr>
  </tbody>
</table>

<p>Network interfaces are points of connection between a computer and a network.</p>

<table>
  <thead>
    <tr>
      <th>Command</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ip</code></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ifconfig</code></td>
      <td>Display active network interfaces</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">hostname</code></td>
      <td>Display current host name</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">host</code></td>
      <td>Show IP address for a domain name</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">nslookup</code></td>
      <td>Same</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ping</code></td>
      <td>Check whether remote host is alive and responding</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">route</code></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">netstat</code></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">nmap</code></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">wget</code></td>
      <td>Download web pages</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">curl</code></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ssh</code></td>
      <td>Crytographic network protocol</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">scp</code></td>
      <td>Secure copy between 2 network hosts, uses SSH protocol</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ssh &lt;hostname&gt; &lt;command&gt;</code></td>
      <td>SSH Tunnel</td>
    </tr>
  </tbody>
</table>

<hr />

<p>References:</p>
<ul>
  <li><a href="https://youtu.be/sWbUDq4S6Y8">https://youtu.be/sWbUDq4S6Y8</a></li>
</ul>]]></content><author><name>tlouarn</name></author><category term="linux" /><summary type="html"><![CDATA[Linux is an open-source operating system. Its core components are a boot loader, a kernel, basic services including a shell, and a package manager. Linux can also come with a display manager and some applications (like LibreOffice or GIMP).]]></summary></entry><entry><title type="html">Understanding Quicksort</title><link href="https://tlouarn.com/2023/07/21/understanding-quicksort.html" rel="alternate" type="text/html" title="Understanding Quicksort" /><published>2023-07-21T00:00:00+00:00</published><updated>2023-07-21T00:00:00+00:00</updated><id>https://tlouarn.com/2023/07/21/understanding-quicksort</id><content type="html" xml:base="https://tlouarn.com/2023/07/21/understanding-quicksort.html"><![CDATA[<p><strong>Quicksort</strong> is a divide-and-conquer sorting algorithm with an average time complexity of \(O(n \log(n))\) and a space complexity of \(O(log(n))\). The list is traversed and rearranged recursively until each pivot value finds its correct position.</p>

<h1 id="partitioning">Partitioning</h1>

<p>Before we dive into Quicksort, we need to understand what is partitioning. Given an array of \(n\) elements, we pick one element that will serve as pivot and place all the smaller elements on its left and all the bigger elements on its right. By doing so, we position the pivot where it should be.</p>

<p>In the following example, we consider an unordered array of integers from 1 to 10. We choose the first value as the pivot. We then rearrange the array so that the smaller values are on its left and the bigger values are on its right.</p>

<p><img src="/assets/images/tlouarn-partitioning.drawio.svg" alt="Partitioning a list of integers using its first element as the pivot" />
<em>Partitioning a list of integers using its first element as the pivot.</em></p>

<p>Note that when moving smaller and bigger elements, their relative order may change: we say that Quicksort is <strong>not stable</strong>. In contrast, a stable sorting algorithm would preserve the relative order of equal elements in the sorted output.</p>

<p>A simple way to partition would be to initialize three subsets, loop through the array and allocate each element to the correct subset. Such a function would do the job but would not be memory-efficient since it would use three intermediary lists and return the partitioned array in a new list.</p>

<p>As you have probably guessed, we can be smarter than that and partition the array <strong>in-place</strong>, that is without creating new lists. To do so, we traverse the array once and swap elements so that all elements smaller than the pivot end up “towards the left” and all the elements bigger than the pivot end up “towards the right”. We then put the pivot value at its correct position.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">partition</span><span class="p">(</span><span class="n">array</span><span class="p">:</span> <span class="nb">list</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
    <span class="s">"""
    In-place partitioning using the first element as the pivot.
    """</span>

    <span class="c1"># Choose the first element as the pivot
</span>    <span class="n">pivot</span> <span class="o">=</span> <span class="n">array</span><span class="p">[</span><span class="mi">0</span><span class="p">]</span>

    <span class="c1"># `index` keeps track of the smaller subset
</span>    <span class="c1"># We initialize it with 1
</span>    <span class="n">index</span> <span class="o">=</span> <span class="mi">1</span>

    <span class="c1"># Loop through the values (starting after the pivot)
</span>    <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="n">array</span><span class="p">)):</span>

        <span class="c1"># If we find a value smaller than the pivot,
</span>        <span class="c1"># swap it with the current next element
</span>        <span class="c1"># after the "smaller" subset
</span>        <span class="k">if</span> <span class="n">array</span><span class="p">[</span><span class="n">i</span><span class="p">]</span> <span class="o">&lt;</span> <span class="n">pivot</span><span class="p">:</span>
            <span class="n">array</span><span class="p">[</span><span class="n">i</span><span class="p">],</span> <span class="n">array</span><span class="p">[</span><span class="n">index</span><span class="p">]</span> <span class="o">=</span> <span class="n">array</span><span class="p">[</span><span class="n">index</span><span class="p">],</span> <span class="n">array</span><span class="p">[</span><span class="n">i</span><span class="p">]</span>
            <span class="n">index</span> <span class="o">+=</span> <span class="mi">1</span>

    <span class="c1"># At this stage, `index - 1` represents the last
</span>    <span class="c1"># value in the smaller subset; swap it with the pivot
</span>    <span class="c1"># This way the pivot is placed just after the smaller subset
</span>    <span class="n">array</span><span class="p">[</span><span class="mi">0</span><span class="p">],</span> <span class="n">array</span><span class="p">[</span><span class="n">index</span> <span class="o">-</span> <span class="mi">1</span><span class="p">]</span> <span class="o">=</span> <span class="n">array</span><span class="p">[</span><span class="n">index</span> <span class="o">-</span> <span class="mi">1</span><span class="p">],</span> <span class="n">array</span><span class="p">[</span><span class="mi">0</span><span class="p">]</span>
</code></pre></div></div>

<h1 id="quicksort">Quicksort</h1>

<p>Quicksort works by recursively partitioning the “smaller” and “bigger” subsets. By doing so, we place each pivot at its correct position given the subset we are in, then process the new “smaller” and “bigger” subsets, etc.</p>

<p>Let us now implement Quicksort using in-place partitioning. For that, we need to modify our <code class="language-plaintext highlighter-rouge">partition()</code> function. Since the function will be used on different subsets of a <strong>same list</strong>, we need to add a start and an end to its signature so that it knows where to start and where to stop. This way, the same function can operate on different segments of a same list from different layers of the call stack. We also need to have it return the position of the pivot: this way, we can call it again on the “smaller” subset (i.e. up until the pivot position) and on the “bigger” subset (i.e. from the pivot position until the end).</p>

<p>We can rewrite it as below:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">partition</span><span class="p">(</span><span class="n">array</span><span class="p">:</span> <span class="nb">list</span><span class="p">,</span> <span class="n">start</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">end</span><span class="p">:</span> <span class="nb">int</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span>
    <span class="s">"""
    In-place partitioning using the first element as the pivot.
    """</span>

    <span class="c1"># Choose the first element as the pivot
</span>    <span class="n">pivot</span> <span class="o">=</span> <span class="n">array</span><span class="p">[</span><span class="n">start</span><span class="p">]</span>

    <span class="c1"># `index` keeps track of the smaller subset
</span>    <span class="c1"># We initialize it with start + 1
</span>    <span class="n">index</span> <span class="o">=</span> <span class="n">start</span> <span class="o">+</span> <span class="mi">1</span>

    <span class="c1"># Loop through the values (starting after the pivot)
</span>    <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">start</span> <span class="o">+</span> <span class="mi">1</span><span class="p">,</span> <span class="n">end</span><span class="p">):</span>

        <span class="c1"># If we find a value smaller than the pivot,
</span>        <span class="c1"># swap it with the current next element
</span>        <span class="c1"># after the "smaller" subset
</span>        <span class="k">if</span> <span class="n">array</span><span class="p">[</span><span class="n">i</span><span class="p">]</span> <span class="o">&lt;</span> <span class="n">pivot</span><span class="p">:</span>
            <span class="n">array</span><span class="p">[</span><span class="n">i</span><span class="p">],</span> <span class="n">array</span><span class="p">[</span><span class="n">index</span><span class="p">]</span> <span class="o">=</span> <span class="n">array</span><span class="p">[</span><span class="n">index</span><span class="p">],</span> <span class="n">array</span><span class="p">[</span><span class="n">i</span><span class="p">]</span>
            <span class="n">index</span> <span class="o">+=</span> <span class="mi">1</span>

    <span class="c1"># At this stage, `index - 1` represents the last
</span>    <span class="c1"># value in the smaller subset; swap it with the pivot
</span>    <span class="c1"># This way the pivot is placed just after the smaller subset
</span>    <span class="n">array</span><span class="p">[</span><span class="n">start</span><span class="p">],</span> <span class="n">array</span><span class="p">[</span><span class="n">index</span> <span class="o">-</span> <span class="mi">1</span><span class="p">]</span> <span class="o">=</span> <span class="n">array</span><span class="p">[</span><span class="n">index</span> <span class="o">-</span> <span class="mi">1</span><span class="p">],</span> <span class="n">array</span><span class="p">[</span><span class="n">start</span><span class="p">]</span>

    <span class="c1"># Return the index of the pivot
</span>    <span class="k">return</span> <span class="n">index</span> <span class="o">-</span> <span class="mi">1</span>
</code></pre></div></div>

<p>Finally, we can write the Quicksort algorithm as below:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">quicksort</span><span class="p">(</span><span class="n">array</span><span class="p">:</span> <span class="nb">list</span><span class="p">,</span> <span class="n">start</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">end</span><span class="p">:</span> <span class="nb">int</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
    <span class="s">"""
    In-place Quicksort implementation.
    """</span>

    <span class="c1"># Base condition
</span>    <span class="k">if</span> <span class="n">start</span> <span class="o">&lt;</span> <span class="n">end</span><span class="p">:</span>

        <span class="c1"># Partition a given subset of the array
</span>        <span class="c1"># and store the position of the pivot
</span>        <span class="n">pivot</span> <span class="o">=</span> <span class="n">partition</span><span class="p">(</span><span class="n">array</span><span class="p">,</span> <span class="n">start</span><span class="p">,</span> <span class="n">end</span><span class="p">)</span>

        <span class="c1"># Recursive call on the "smaller" subset
</span>        <span class="n">quicksort</span><span class="p">(</span><span class="n">array</span><span class="p">,</span> <span class="n">start</span><span class="p">,</span> <span class="n">pivot</span><span class="p">)</span>

        <span class="c1"># Recursive call on the "bigger" subset
</span>        <span class="n">quicksort</span><span class="p">(</span><span class="n">array</span><span class="p">,</span> <span class="n">pivot</span> <span class="o">+</span> <span class="mi">1</span><span class="p">,</span> <span class="n">end</span><span class="p">)</span>
</code></pre></div></div>

<p>The <strong>base condition</strong> of our recursive algorithm is that it only runs when <code class="language-plaintext highlighter-rouge">start</code> is strictly less than <code class="language-plaintext highlighter-rouge">end</code>.  The reason for that is: when we reach a  subset of 1 element, the partitioning function will not do anything and return the position of the pivot, which is equal to <code class="language-plaintext highlighter-rouge">start</code>. At this point the next two calls to <code class="language-plaintext highlighter-rouge">quicksort()</code> further up the call stack will return nothing, and ultimately this branch of recursion will be closed.</p>

<h1 id="complexity-analysis">Complexity analysis</h1>

<p>Let’s first look at the time complexity. On average, the number of times the array will be divided into subsets is \(log(n)\), and at each pass we traverse the whole array, which takes \(n\) operations. The average time complexity is therefore \(O(n log(n))\).</p>

<p>The worst time complexity happens when the array is already sorted. In that case, each pair of subset will be of type \([ 1 : n-1 ]\) and the array will have to be partitioned \(n\) times. The worst-case time complexity is therefore \(O(n2)\).</p>

<p>When it comes to space complexity analysis, there are two things to consider: the actual memory used for variables and the memory used by the call stack. Regarding the first one, Quicksort’s footprint is minimal since we swap all elements in-place (complexity of \(O(1)\)). Regarding the call stack though, the space complexity is on average \(O(log(n))\) since we need to divide the array \(log(n)\) times, and it can be \(O(n)\) in the worst case.</p>

<h1 id="conclusion">Conclusion</h1>

<p>In this article we presented the Quicksort algorithm along with its recursive Python implementation. Quicksort is time-efficient due to partitioning and space-efficient due to the partitioning being done in-place.</p>

<p>There is some flexibility with the algorithm: so far we have always selected the first element of the list as pivot, but it is possible to choose the last element, the middle element, a random element, etc. In fact, choosing a random element usually mitigates the risk of encountering a worst-case scenario.</p>

<p>As usual with sorting algorithms, the best algorithm is the one most suited for the data. Although Quicksort is often the fastest algorithm, it can’t beat good old BubbleSort on an already-sorted list for instance (but then again, who would want to sort a sorted list 🤔?).</p>

<hr />

<p>References:</p>
<ul>
  <li><a href="https://me.dt.in.th/page/quicksort/">https://me.dt.in.th/page/quicksort/</a></li>
  <li><a href="https://www.enjoyalgorithms.com/blog/quick-sort-algorithm">https://www.enjoyalgorithms.com/blog/quick-sort-algorithm</a></li>
  <li><a href="https://cs.stackexchange.com/questions/144424/stability-of-quicksort-algorithm">https://cs.stackexchange.com/questions/144424/stability-of-quicksort-algorithm</a></li>
  <li><a href="https://stackoverflow.com/questions/18262306/quicksort-with-python">https://stackoverflow.com/questions/18262306/quicksort-with-python</a></li>
</ul>]]></content><author><name>tlouarn</name></author><category term="algorithm" /><category term="python" /><summary type="html"><![CDATA[Quicksort is a divide-and-conquer sorting algorithm with an average time complexity of \(O(n \log(n))\) and a space complexity of \(O(log(n))\). The list is traversed and rearranged recursively until each pivot value finds its correct position.]]></summary></entry><entry><title type="html">Hosting a Ghost instance on AWS EC2</title><link href="https://tlouarn.com/2023/07/12/hosting-ghost-on-aws-ec2.html" rel="alternate" type="text/html" title="Hosting a Ghost instance on AWS EC2" /><published>2023-07-12T00:00:00+00:00</published><updated>2023-07-12T00:00:00+00:00</updated><id>https://tlouarn.com/2023/07/12/hosting-ghost-on-aws-ec2</id><content type="html" xml:base="https://tlouarn.com/2023/07/12/hosting-ghost-on-aws-ec2.html"><![CDATA[<h1 id="a-ghost-in-the-shell">A Ghost in the shell</h1>

<p>After a bit of browsing where I revisited Hugo and a few other systems, I stumbled upon <a href="https://ghost.org/">Ghost</a> and decided to give it a try. Ghost is an open-source publishing platform written in JavaScript (Node.js) with built-in newsletter and subscription functionalities. It also boasts a powerful online editor to write posts directly from the browser. You can either host it on your own or use the paid managed hosting. Since I enjoy making my life more complicated, I thought I would setup an instance myself using a micro <a href="https://aws.amazon.com/pm/ec2">AWS EC2</a>.</p>

<p>The official Ghost documentation assumes you’re using MySQL as a database. After several installation attempts, I found that MySQL was consistently bringing my EC2 micro instance to its knees: the CPU would spike, memory would saturate and the instance would become unresponsive. From there, I could either run Ghost on a more powerful (but more costly) EC2 instance type, or switch the default database for SQLite. Because the static website was to be served by CloudFront, the database would never be a bottleneck so I chose to replace MySQL with SQLite. As a bonus point, backups became trivial: all I had to do was to copy the whole Ghost folder including the SQLite file into an S3 bucket. And when I finally completed the installation and SSH’ed into the EC2, there it was, <strong>the Ghost in the shell</strong>.</p>

<h1 id="installation">Installation</h1>

<p><em>This guide assumes some familiarity with the AWS ecosystem. As usual, I am not giving exact instructions since the AWS interface tends to change quickly, but the main principles should remain the same. One thing to remember: when creating resources in AWS, always ensure you’re in the correct region (top-right corner of the screen).</em></p>

<p>Start by creating a <strong>Virtual Private Cloud</strong>. The VPC provides essential networking infrastructure and ensures your EC2 instance runs in a secured, dedicated environment within AWS. Then set up a <strong>Security Group</strong>. The Security Group acts as a virtual firewall for the EC2 instance. Make sure the Security Group allows SSH (port 22), HTTP (port 80) and HTTPS (port 443) so the EC2 can be accessed from the web. Then go to the EC2 dashboard and launch a new <strong>t2.micro</strong> instance with an Ubuntu <strong>Amazon Machine Image</strong> (AMI). Attach the instance to the VPC and the Security Group. Generate a SSH key pair and download the <code class="language-plaintext highlighter-rouge">.pem</code> file. The instance is now accessible, but its IP will change every time it stops and starts. To prevent this, assign an <strong>Elastic IP</strong> to your EC2 instance. You can now connect to your instance using the SSH key generated earlier as well as the Elastic IP. Note that the default username is usually <code class="language-plaintext highlighter-rouge">ubuntu</code>:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ssh <span class="nt">-i</span> /path/to/your-key.pem ubuntu@your-elastic-ip
</code></pre></div></div>

<p>Following the official Ghost installation guide, install <strong>Ghost</strong> onto your EC2 instance but use SQLite instead of MySQL to avoid the resource overload described before. Register a custom domain name for your blog in <strong>Route 53</strong> and create a <strong>Hosted Zone</strong> with the necessary DNS records. In particular, create a <strong>A record</strong> pointing the domain to the Elastic IP of the EC2 instance. This will direct traffic from the domain to the blog. We now need to setup the DNS using <strong>CloudFront</strong>, but to do so we need an HTTPS certificate. Using <strong>AWS Certificate Manager</strong> (ACM), request a free SSL certificate for your domain and validate it via DNS using Route 53. This will enable HTTPS traffic to your blog. Now you can setup a CloudFront distribution of your glob using the EC2 Elastic IP as the origin, the ACM certificate for HTTPS and leave the default cache behavior.</p>

<p>Finally, update Ghost configuration by editing <code class="language-plaintext highlighter-rouge">config.production.json</code> to set your domain, enable HTTPS and configure SQLite as the database. You can now access your blog via <code class="language-plaintext highlighter-rouge">https://yourblog.com</code>. Optionally, you can setup a <strong>CloudWatch</strong> to monitor the EC2 performance and alert for high resource usage or downtime.</p>

<h1 id="additionals-scripts">Additionals scripts</h1>

<p>I wanted to have a regular backup of the blog into an <strong>S3</strong> bucket. To do so, I created a custom bucket named <code class="language-plaintext highlighter-rouge">backup.myblog.com</code> and added the below script in <code class="language-plaintext highlighter-rouge">/var/local/</code>. This script copies the whole Ghost folder including the SQLite file into a tarball and copies it to the S3 bucket.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># backup.sh</span>

<span class="nb">date</span><span class="o">=</span><span class="si">$(</span><span class="nb">date</span> +<span class="s2">"%Y-%m-%d"</span><span class="si">)</span>
<span class="nv">filename</span><span class="o">=</span><span class="nv">$date</span>.backup.myblog.com.tar.gz
<span class="nb">source</span><span class="o">=</span>/var/www/myblog/content
<span class="nv">local_dest</span><span class="o">=</span>/var/backups
<span class="nv">remote_dest</span><span class="o">=</span>s3://backup.myblog.com
<span class="nb">tar</span> <span class="nt">-czf</span> <span class="nv">$local_dest</span>/<span class="nv">$filename</span> <span class="nv">$source</span>
aws s3 <span class="nb">cp</span> <span class="nv">$local_dest</span>/<span class="nv">$filename</span> <span class="nv">$remote_dest</span>
<span class="nb">rm</span> <span class="nv">$local_dest</span>/<span class="nv">$filename</span>
</code></pre></div></div>

<p>Ghost also needs some help to purge unused images (images that used to be inserted in a post but are not anymore following some editing). This feature is not available within Ghost so you have to rely on a third-party script named <a href="https://github.com/ghostboard/ghost-purge-images">ghost-purge-images</a> and available as an <strong>NPM package</strong>. This script requires access keys that have to be generated from the Ghost interface. Get the API keys, install the NPM package and add the below script in <code class="language-plaintext highlighter-rouge">/var/local</code> as well:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># purge.sh</span>

ghost-purge-images purge <span class="nt">--content-key</span><span class="o">=</span>XXX <span class="nt">--admin-key</span><span class="o">=</span>XXX
</code></pre></div></div>

<p>Now you should see both scripts in <code class="language-plaintext highlighter-rouge">/var/local/</code>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cd</span> /var/local
<span class="nb">ls

</span>backup.sh purge.sh
</code></pre></div></div>

<p>Finally, to automate the tasks, simply sudo into the crontab and add the lines below.</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo </span>crontab <span class="nt">-u</span> root <span class="nt">-e</span>
</code></pre></div></div>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>0 1 <span class="k">*</span> <span class="k">*</span> <span class="k">*</span> /var/local/backup.sh
0 1 <span class="k">*</span> <span class="k">*</span> <span class="k">*</span> /var/local/purge.sh
</code></pre></div></div>]]></content><author><name>tlouarn</name></author><category term="web" /><category term="aws" /><summary type="html"><![CDATA[A Ghost in the shell]]></summary></entry><entry><title type="html">Breadth-first search algorithm</title><link href="https://tlouarn.com/2023/07/09/breadth-first-search-algorithm.html" rel="alternate" type="text/html" title="Breadth-first search algorithm" /><published>2023-07-09T00:00:00+00:00</published><updated>2023-07-09T00:00:00+00:00</updated><id>https://tlouarn.com/2023/07/09/breadth-first-search-algorithm</id><content type="html" xml:base="https://tlouarn.com/2023/07/09/breadth-first-search-algorithm.html"><![CDATA[<p>In <a href="/2023-07-06-graph-theory-101">Graph Theory 101</a>, we introduced five concepts used to describe a graph: direction, weight, cycles, connectivity and density. In <a href="2023-07-06-modeling-graphs-using-python.md">Modeling graphs using Python</a>, we saw how to represent a graph using either an adjacency matrix or an adjacency list.</p>

<p>It is now time to learn how to traverse a connected graph. In this post, we introduce the Breadth-First Search (<strong>BFS</strong>) and the Depth-First Search (<strong>DFS</strong>) algorithms. BFS progresses layer by layer, listing all the children of a given node. In contrast, DFS would delve deep into a given branch all the way to the leaf before backtrackig and exploring the next branch. We can run a BFS or a DFS on either an adjacency list or an adjacency matrix.</p>

<h1 id="example">Example</h1>

<p>In this article we will consider the example graph below to explain BFS and DFS.</p>

<p><img src="/assets/images/tlouarn-breadth-first-search-algorithm-example-connected-tree.drawio.svg" alt="Example of connected tree" />
<em>Figure 1: example connected tree</em></p>

<p>Let us build this graph as an adjacency list using Python:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">collections</span> <span class="kn">import</span> <span class="n">defaultdict</span>

<span class="c1"># Input
</span><span class="n">edges</span> <span class="o">=</span> <span class="p">[[</span><span class="s">"A"</span><span class="p">,</span> <span class="s">"B"</span><span class="p">],</span> <span class="p">[</span><span class="s">"A"</span><span class="p">,</span> <span class="s">"C"</span><span class="p">],</span> <span class="p">[</span><span class="s">"B"</span><span class="p">,</span> <span class="s">"D"</span><span class="p">],</span> <span class="p">[</span><span class="s">"B"</span><span class="p">,</span> <span class="s">"E"</span><span class="p">],</span> <span class="p">[</span><span class="s">"C"</span><span class="p">,</span> <span class="s">"F"</span><span class="p">],</span> <span class="p">[</span><span class="s">"C"</span><span class="p">,</span> <span class="s">"G"</span><span class="p">]]</span>

<span class="c1"># Build adjacency list
</span><span class="n">graph</span> <span class="o">=</span> <span class="n">defaultdict</span><span class="p">(</span><span class="nb">list</span><span class="p">)</span>
<span class="k">for</span> <span class="n">edge</span> <span class="ow">in</span> <span class="n">edges</span><span class="p">:</span>
    <span class="n">graph</span><span class="p">[</span><span class="n">edge</span><span class="p">[</span><span class="mi">0</span><span class="p">]].</span><span class="n">append</span><span class="p">(</span><span class="n">edge</span><span class="p">[</span><span class="mi">1</span><span class="p">])</span>
    <span class="n">graph</span><span class="p">[</span><span class="n">edge</span><span class="p">[</span><span class="mi">1</span><span class="p">]].</span><span class="n">append</span><span class="p">(</span><span class="n">edge</span><span class="p">[</span><span class="mi">0</span><span class="p">])</span>
</code></pre></div></div>

<h1 id="bfs-algorithm">BFS algorithm</h1>

<p>Let us look at the below graph to understand how BFS works: from a given starting node, we list all the children. We then explore each child, and for each one of them, we list all its children. We then move another level down, etc.</p>

<p><img src="/assets/images/tlouarn-breadth-first-search-algorithm-overview.drawio.svg" alt="Visual overview of the BFS algorithm" />
<em>Figure 2: visual overview of the BFS algorithm</em></p>

<p>In the above example, starting from A we list B and C. Moving to B, we list D and E. Moving to C, we list F and G. Moving to D, E, F and finally G, we realize they are leaf nodes so we don’t list anything. When the list is empty, the algorithm stops.</p>

<p>Figure 1 is acyclic, but BFS needs to be able to explore cyclic graphs without getting trapped into infinite loops. To do so, we maintain a list of visited nodes and only add unvisited nodes to the “next nodes” list.</p>

<p>To implement BFS, we use a <strong>queue</strong> data structure (<code class="language-plaintext highlighter-rouge">deque</code> object in Python).</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">collections</span> <span class="kn">import</span> <span class="n">deque</span>

<span class="n">AdjacencyList</span> <span class="o">=</span> <span class="nb">dict</span><span class="p">[</span><span class="nb">set</span><span class="p">]</span>

<span class="k">def</span> <span class="nf">bfs</span><span class="p">(</span><span class="n">graph</span><span class="p">:</span> <span class="n">AdjacencyList</span><span class="p">,</span> <span class="n">node</span><span class="p">:</span> <span class="nb">int</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
    <span class="n">visited</span> <span class="o">=</span> <span class="nb">set</span><span class="p">()</span>
    <span class="n">queue</span> <span class="o">=</span> <span class="n">deque</span><span class="p">()</span>
    <span class="n">queue</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">node</span><span class="p">)</span>

    <span class="k">while</span> <span class="n">queue</span><span class="p">:</span>
        <span class="n">node</span> <span class="o">=</span> <span class="n">queue</span><span class="p">.</span><span class="n">popleft</span><span class="p">()</span>
        <span class="k">if</span> <span class="n">node</span> <span class="ow">not</span> <span class="ow">in</span> <span class="n">visited</span><span class="p">:</span>
            <span class="n">visited</span><span class="p">.</span><span class="n">add</span><span class="p">(</span><span class="n">node</span><span class="p">)</span>
            <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"</span><span class="si">{</span><span class="n">node</span><span class="si">}</span><span class="s">:"</span><span class="p">,</span> <span class="n">end</span><span class="o">=</span><span class="s">" "</span><span class="p">)</span>

            <span class="n">neighbors</span> <span class="o">=</span> <span class="n">graph</span><span class="p">[</span><span class="n">node</span><span class="p">]</span>
            <span class="k">for</span> <span class="n">neighbor</span> <span class="ow">in</span> <span class="n">neighbors</span><span class="p">:</span>
                <span class="k">if</span> <span class="n">neighbor</span> <span class="ow">not</span> <span class="ow">in</span> <span class="n">visited</span><span class="p">:</span>
                    <span class="n">queue</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">neighbor</span><span class="p">)</span>

</code></pre></div></div>

<p>Let us run the code on our example to see the order in which the nodes were explored:</p>
<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>A B C D E F G
</code></pre></div></div>

<p>What we do with BFS is very versatile: we can use BFS to explore all connected nodes, or to look for a specific node. We can use it to add edges etc.</p>

<h1 id="dfs-algorithm">DFS algorithm</h1>

<p>Iterative implementation</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code>


</code></pre></div></div>]]></content><author><name>tlouarn</name></author><category term="algorithms" /><category term="python" /><summary type="html"><![CDATA[In Graph Theory 101, we introduced five concepts used to describe a graph: direction, weight, cycles, connectivity and density. In Modeling graphs using Python, we saw how to represent a graph using either an adjacency matrix or an adjacency list.]]></summary></entry><entry><title type="html">Graph Theory 101</title><link href="https://tlouarn.com/2023/07/06/graph-theory-101.html" rel="alternate" type="text/html" title="Graph Theory 101" /><published>2023-07-06T00:00:00+00:00</published><updated>2023-07-06T00:00:00+00:00</updated><id>https://tlouarn.com/2023/07/06/graph-theory-101</id><content type="html" xml:base="https://tlouarn.com/2023/07/06/graph-theory-101.html"><![CDATA[<p>A graph is made of two components: <strong>nodes</strong> (also known as vertices) and <strong>edges</strong> (also known as arcs). Nodes represent entities while edges depict the connections between these entities. For example, in the context of a social network, nodes represent individuals and edges represent the connections between them.</p>

<p>Graphs come in all shapes and forms. This post introduces five key properties to describe and categorize them: direction, weight, cyclicity, connectivity and density.</p>

<p>Table of contents:</p>
<ul id="markdown-toc">
  <li><a href="#directed-and-undirected-graphs" id="markdown-toc-directed-and-undirected-graphs">Directed and undirected graphs</a></li>
  <li><a href="#weighted-and-unweighted-graphs" id="markdown-toc-weighted-and-unweighted-graphs">Weighted and unweighted graphs</a></li>
  <li><a href="#connecting-the-dots" id="markdown-toc-connecting-the-dots">Connecting the dots</a></li>
  <li><a href="#cyclic-and-acyclic-graphs" id="markdown-toc-cyclic-and-acyclic-graphs">Cyclic and acyclic graphs</a></li>
  <li><a href="#connected-and-disconnected-graphs" id="markdown-toc-connected-and-disconnected-graphs">Connected and disconnected graphs</a></li>
  <li><a href="#density" id="markdown-toc-density">Density</a></li>
  <li><a href="#trees" id="markdown-toc-trees">Trees</a></li>
  <li><a href="#conclusion" id="markdown-toc-conclusion">Conclusion</a></li>
</ul>

<h1 id="directed-and-undirected-graphs">Directed and undirected graphs</h1>

<p><img src="/assets/images/tlouarn-graph-theory-101-directed-unweighted-graph.png" alt="Directed Graph" /></p>

<p>In a directed graph, edges indicate a one-way relationship between nodes. Each edge has a specific direction. In other words:</p>

<p>\[ edge(A,B)≠edge(B,A) \]</p>

<p>Some edges in a directed graph can be bi-directional. In Figure 2 for instance, the edge between nodes A and C is bi-directional. A directed graph where all edges are bi-directional becomes an undirected graph.</p>

<p>Examples of directed graphs include followers in a social network, city maps and corporate holdings. In a social network like Instagram, if Alice follows Bob, it does not mean that Bob follows Alice. In a city, some streets can be only one-way. Regarding corporate holdings, if company A owns company B, it does not mean that company B owns company A.</p>

<p><img src="/assets/images/tlouarn-graph-theory-101-undirected-unweighted-graph.png" alt="Undirected Graph" />
<em>Figure 1: an example of undirected graph</em></p>

<p>In an undirected graph, nodes are linked together but edges do not have a direction. If node A is linked to node B, then node B is also linked to node A. Edges are symmetric, they model two-way relationships and can be traversed in either direction. In other words:</p>

<p>\[ edge(A,B)=edge(B,A) \]</p>

<p>Examples of undirected graphs include connections in a social network and molecular structures. In a social network, if Alice is connected to Bob then Bob is in effect connected to Alice. In molecular structures, we can model atoms as nodes and bonds as edges.</p>

<h1 id="weighted-and-unweighted-graphs">Weighted and unweighted graphs</h1>

<p>Unweighted graphs define connections but do not quantity these links. By convention, the weight of every edge in an unweighted graph is considered to be one. A weight of zero means no edge.</p>

<p>Typical examples of unweighted graphs include connections in a social network and hyperlinks between web pages. In a social network, connections between users simply exist or don’t exist, but they all have the same importance. Similarly, web pages are either linked or not linked, but each hyperlink is of similar importance (the number of links pointing to a web page, on the other hand, has value - it is the pillar of <a href="http://infolab.stanford.edu/~backrub/google.html?ref=tlouarn.com">Google’s original PageRank algorithm</a>).</p>

<p><img src="/assets/images/tlouarn-graph-theory-101-undirected-weighted-graph.png" alt="Undirected Weighted Graph" /></p>

<p>In a weighted graph, each edge is given a numerical weight. This weight can represent a cost, a distance, a duration etc. Note that in a directed graph, the edge pointing from A to B can have a different value than the edge pointing from B to A.</p>

<p>We can model distances between cities or conversions between units as weighted graphs. The first example is useful to compute the classic traveling salesman problem. In the second example, each unit is a node and the conversion factors (if they exist) are modeled as directed weighted edges.</p>

<h1 id="connecting-the-dots">Connecting the dots</h1>

<p>As you have probably understood by now, direction and weight are not mutually exclusive properties. For example, Figure 1 is both undirected and unweighted whereas Figure 3 is undirected but weighted.</p>

<p>Let’s summarize the four categories of graphs seen so far into a simple matrix. For each category, we give a real-life example expressed in the form edges between nodes:</p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Weighted</th>
      <th>Unweighted</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Directed</td>
      <td>Conversions between units</td>
      <td>Hyperlinks between web pages</td>
    </tr>
    <tr>
      <td>Undirected</td>
      <td>Distances between cities</td>
      <td>Connections between individuals</td>
    </tr>
  </tbody>
</table>

<h1 id="cyclic-and-acyclic-graphs">Cyclic and acyclic graphs</h1>

<p>A cycle is a non-empty path in which the first and the last nodes are equal. A graph containing at least one cycle is called cyclic.</p>

<p>Transportation networks and social networks usually exhibit cyclic properties. In a transportation network, trucks can move goods from A to B, then from B to C and back from C to A. In a social network, it can emerge that Alice follows Bob, Bob follows Carol and Carol follows Alice.</p>

<p><img src="/assets/images/tlouarn-graph-theory-101-directed-acyclic-graph.png" alt="Acyclic Graph" /></p>

<p>An acyclic graph does not have any cycle. When visiting the graph from node to node, one will never visit the same node twice.</p>

<p>In <a href="https://airflow.apache.org/docs/apache-airflow/1.10.12/concepts.html?ref=tlouarn.com">AirFlow</a>, collections of tasks are defined as Directed Acyclic Graphs (or DAGs). It simply means that the tasks are linked together by edges that have a direction but do not form cycles. This way, we can specify an order of execution and avoid the formation of infinite loops.</p>

<h1 id="connected-and-disconnected-graphs">Connected and disconnected graphs</h1>

<p>We define a path as a sequence of edges. In a connected graph, there is a path between each node of the graph. For instance, the graph of a road network is usually connected since it’s unlikely that a road sits by itself away from all other roads.</p>

<p>In a disconnected graph: all nodes are not necessarily linked by a path. For example, constellations or archipelagos can be modeled using disconnected graphs.</p>

<p><img src="/assets/images/tlouarn-graph-theory-101-disconnected-graph.png" alt="Disconnected Graph" /></p>

<h1 id="density">Density</h1>

<p>The maximal number of edges in an undirected graph of \(n\) nodes is \(n∗(n−1)/2\). Logically, in a directed graph, it is \(n∗(n−1)\) edges.</p>

<p>We can therefore describe graphs by their density:</p>

<table>
  <thead>
    <tr>
      <th>Name</th>
      <th>Definition</th>
      <th>Density</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>null</strong> graph</td>
      <td>edgeless disconnected graph</td>
      <td>\(0\)</td>
    </tr>
    <tr>
      <td><strong>sparse</strong> graph</td>
      <td>number of edges close to the minimum</td>
      <td>\(≳0\)</td>
    </tr>
    <tr>
      <td><strong>dense</strong> graph</td>
      <td>number of edges close to the maximum</td>
      <td>\(≲1\)</td>
    </tr>
    <tr>
      <td><strong>complete</strong> graph</td>
      <td>each node has an edge to every other node</td>
      <td>\(1\)</td>
    </tr>
  </tbody>
</table>

<p><img src="/assets/images/tlouarn-graph-theory-101-complete-graph.png" alt="Complete Graph" /></p>

<h1 id="trees">Trees</h1>

<p>A tree is a connected acyclic graph.</p>

<p>In a tree, edges are named branches and nodes without children are called leaf nodes. In computer science, trees are also defined by the existence of a root (i.e. a starting node) and are usually assumed to be directed. For instance, in Figure 6, node A is the root and nodes D, E, F and G are leaf nodes.</p>

<p>A disconnected acyclic graph, i.e. a collection of trees, is called a <strong>forest</strong>.</p>

<p>An example of tree structure that you probably use everyday is the file system, where each directory is a node. The Document Object Model (DOM) is also a tree. Other examples of trees include family trees and decision trees.</p>

<h1 id="conclusion">Conclusion</h1>

<p>In this article we have reviewed the basic properties used to describe a graph. By now you should be familiar with the notions of direction, weight, cycles, connectivity and density. These properties are not mutually exclusive: a graph can be directed, unweighted, acyclic and connected but sparse for instance.</p>

<p>Ordinary graphs can be generalized into more abstract structures such as multigraphs (where two nodes can be linked by more than one or two edges) and hypergraphs (where an edge is an area linking an arbitrary number of nodes).</p>

<p>In the <a href="/2023/07/06/modeling-graphs-using-python.html">next post</a> we will look at how to model ordinary graphs using Python.</p>]]></content><author><name>tlouarn</name></author><category term="programming" /><summary type="html"><![CDATA[A graph is made of two components: nodes (also known as vertices) and edges (also known as arcs). Nodes represent entities while edges depict the connections between these entities. For example, in the context of a social network, nodes represent individuals and edges represent the connections between them.]]></summary></entry></feed>